
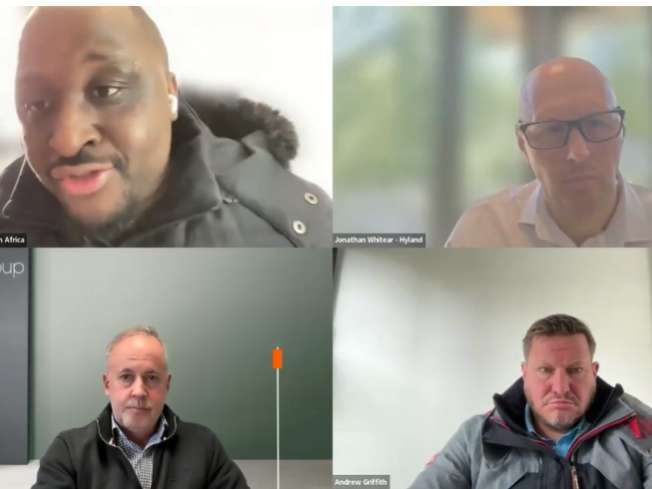
In a recent CIO South Africa webinar exploring the foundations of an AI-ready enterprise, Jonathan Whitear, specialist sales: EMEA and APAC at Hyland, Justin Parry, CEO: Content services at Visions Group, and Andrew Griffith, MD at Information Genetics, unpacked why the success of any AI strategy depends less on the model chosen and more on whether an organisation's content is connected, governed and understandable.
Titled AI Bottleneck - Why Content, Context and Governance Decide Your Results, the session set out to answer a question increasingly on the minds of CIOs: why do so many AI initiatives stall once they move beyond the proof-of-concept stage?
Opening the session, Jonathan framed the distinction between general-purpose AI and AI operating “in context” of a specific business. Asking a tool such as Copilot or ChatGPT a question, he explained, means drawing on the entire internet. “You’re asking the world and you’re getting a response back. It’s not necessarily considered about your business, it's not considered about what you do.”
A context engine, by contrast, narrows that universe to an organisation’s own information. “It’s like using just your intranet to do this,” he said. “The context engine is able to remove the internet and make it more of your intranet size. And that gives you the ability, when you start wanting decisions, wanting to ask questions – it's restricting the available information, not the power of the AI, but the available information to what you know and what you can do.”
For Jonathan, the starting point for any organisation is not the technology at all. “The simple question is, if you could, what would you want from it, what does it empower you to do?" He urged CIOs to resist being pulled into what he called “the technology wars” among competing LLMs. “What we found when we’re advising people is to pick what you want to get as a result first, then start looking at the technology.”
Asked how these dynamics are playing out locally, Justin observed that South African organisations are moving past early experimentation. “I think we’re seeing a sort of POC fatigue and wanting to move beyond experimentation into more widespread enterprise-scale adoption,” he said. “Getting a chatbot or a copilot going is easy, but getting it to operate reliably against an organisation’s own information is harder.”
South Africa's AI maturity
Jonathan, who works globally, added that South Africa is not lagging behind other markets, despite a common perception to the contrary. “Everybody perceives they’re always behind, but these conversations are very similar when we’re in the US, similar when I’ve been in Japan, similar when I’ve been in the EMEA or the UK or Europe. There’s no difference.” The common challenge everywhere, he said, is proving return on investment.
Turning to governance, Andrew described the state of most organisations’s unstructured data in blunt terms. “Once most organisations start getting into that, they realise that it’s quite a swamp,” he said, pointing to KYC documents, legal contracts, proposals and quotes scattered, which he described as not one repository, but multiple repositories inside an organisation that it is not versioned or governed. He compared the process to construction: “You have to kind of think of it back to how you build a house, right? You first lay the foundation... that unstructured information is the foundation. That’s what’s got to be organised, that’s what’s got to be verified, that’s what’s got to be classified, that’s what’s got to be contextualised.”
Andrew also argued this is not a new problem requiring an entirely new solution. “We actually solved this challenge quite a long time ago with a structured, governed content layer. So it used to be called ECM, that’s obviously a term that’s now outdated and out of fashion, but that's really what you need to do.” He was equally direct about the limits of infrastructure alone. “You can’t organise, verify, classify, contextualise... from infrastructure. A storage bucket is not a content layer.”
Justin agreed that most organisations' content simply isn’t AI-ready in its current state. “And I don’t think it's because organisations have got bad information. They’ve got good information, there’s just an enormous amount of it... it needs the context in order to make those decisions.”
Provenance, trust and auditability
A recurring theme was the need for AI outputs to be traceable back to a verified source – particularly in regulated sectors. Andrew explained that content processed “in context” answers only from “a defined sort of permissioned set of context... and it tells you where each answer came from, and that’s the provenance aspect of this”. He warned that general-purpose models behave differently. “It’s going to review all 10,000 documents, and then it’s going to kind of aggregate that and give you an answer very confidently... those models are great at language, and plausible at everything and kind of accountable for nothing.”
Justin described provenance as “a fancy word for being able to audit. “When you're looking at AI outputs, it’s almost working back to see how did AI come up with that answer?” He cited a medical insurance scenario to illustrate the stakes: “In order to pay that claim, you need to consider a number of different documents around you in that context, and unless you have that contextual grounding, there is a real risk that you’re going to pay it incorrectly, or you miss something within the documents.”
Jonathan added that logging and auditability should be a baseline expectation of any AI supplier. "A very key question that everybody should be asking their supplier of anything related to AI is what's the logging, what's the provenance, what, how are you doing this? The one thing that I’m always consistently asked is, is my result auditable? Can I actually stand behind this?”
The shadow AI risk
The panel also addressed the risk of employees bypassing governed systems altogether by feeding sensitive documents into public tools under deadline pressure. Andrew described this as “shadow AI”. Jonathan warned that once a document is shared with a public model, there is no way to retrieve it “When you put a document in ChatGPT, it’s on the internet forever. You can’t unwind it, you can’t take it back, it’s literally there." He added that the risk extends beyond what a rushed employee might realise is sensitive. “The document is consumed in its whole. You might think you’ll give a page, you don’t know what's on page 9, 10, 11, 12, 15, 20. There could be proprietary information in part of that document you’re just not aware of.”
On where to begin, the panel agreed on a simple prescription: target the most tedious, repetitive work first. “Start with the banal, repetitive, mind-numbing work inside your organisation. Start there,” said Justin. Jonathan agreed this is where the clearest wins lie. “Look for an outcome that people struggle with because it’s mundane, it’s dull... that’s where people can really make a big impact.”
Responding to an audience question on whether AI governance should be continuous rather than a single assessment, Andrew was unequivocal: “It is done up front, but it is done continuously. It is a recurring thing.”
Jonathan agreed, describing the entire discipline as inherently iterative. “Everything with AI is iterative – the prompts you do are iterative, the way you work is iterative, the monitoring is iterative. Nobody’s an expert in this yet, and we’ll look back in two years, five years, and laugh at what we’re doing now."
Closing thoughts
Asked for their parting advice, Justin urged organisations not to fear governance but to embrace it as a permanent discipline. “It's not something you do once off, it’s there to stay.” Andrew called for a measured approach to executive enthusiasm for AI. “The challenge for CIOs and CTOs is to temper the expectations of boards, of CEOs, who just want AI, AI through the organisation – you've got to proceed with caution, and lay the foundation for the agentic enterprise, it’s discipline first."
Jonathan closed with the same question he opened with: “Start with the outcome. What do you want from this first? If you start with a simple question like that, that will give you the background into it, and it’ll probably answer some of your questions as to should I, shouldn’t I be applying this.”
To watch the full webinar, click here.